
Available Resources
This documentation is meant as an addition to the OpenAPI specification that comes with each Qbilon instance reachable viaDocumentation → API Documentation (the specific URL is always <host>/openapi/index.html). This is a Redocly UI that contains the documentation of all individual endpoints. If you have feedback regarding the API or need help, feel free to open a ticket.
Introduction
The Qbilon API is a REST API. This document describes how to use the Qbilon API for reading, writing, deleting, linking, merging and what to expect from it. Qbilon provides a dedicated API in order to allow sophisticated read and write access to its data. This is intended for users who want to either automate a data task from outside of Qbilon or who want to use that API from within a custom task.Authentication
Currently all API endpoints reachable under the path/apiv1/data are secured via basic auth, i.e., each request requires an Authorization header with the value Basic <base64 encoded username:password> . In order to successfully authenticate against the API endpoints you need to have a valid license in place and user roles of ADMIN or ARCHITECT.
Example: Having created a user in Qbilon with username api-user and the password password123, the string api-user:password123 has to be encoded into Base64 format, resulting in YXBpLXVzZXI6cGFzc3dvcmQxMjM=. For making a request to an endpoint, the Authorization header has then the value Basic YXBpLXVzZXI6cGFzc3dvcmQxMjM=.
Multi-Tenancy
Qbilon is per default a multi-tenancy aware application, therefore all API requests have to be augmented with the information about which tenant is targeted via theQbilon-Tenant header. The header has to be sent with all requests to the API endpoints in order for them to work correctly.
The value for it can be found out as an admin by going to Settings → Manage Realm . The tenant name is then shown in the upper-left corner like this:
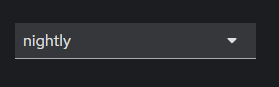
https://nightly.my-company.com then the value for this header and respectively the tenant would be nightly.
Qbilon ID vs. External ID
In the examples mentioned for using the API for reading, writing, deleting, linking, merging, we only usedexternalIds although there are two different types of IDs in Qbilon, the other one being qbilonId. The difference between them is as follows:
- An
externalIdis data source specific, it has only to be unique within the context of the data source/API call that is writing an asset or relation. It can be chosen freely by the author of the data source or the API call. Nevertheless, it must be deterministic: If the same asset “Server 1” is sent twice in two different API calls, then it must have the same ID in both calls. - A
qbilonIdis globally unique and is assigned by Qbilon when a new asset or relation is written to its database. Later on, this ID can be used by a data source/an API call to directly modify existing assets/relations. - Note: Please note that if both ID types are provided, the
qbilonIdtakes precedence without any fallback toexternalIdforqbilonIdsthat have not been found.
Preparing Data Sources
When data is written to Qbilon, it tracks for each created type/asset/relation and each of their properties which data source wrote the respective data. In addition, Qbilon keeps track of theFirst Seen and Last Seen properties for each of them. To be able to do this, all altering actions must be performed in the context of a data source.
Currently, there are three different types of data sources:
Manual: Changes to the data triggered through the UI are tracked via the artificial data source “Manual”. It can also be used as a testing data source when using the API via the fixed ID-2.System: “System” is an artificial data source that is used by the application itself when adding data to assets, e.g., theFirst SeenandLast Seenproperties. It has the fixed ID-1and is forbidden to be used within the API. If it is used anyway, Qbilon will return an error response.Task: Each task in the Qbilon automation engine has a unique ID that can be used as a data source for the writing endpoints. For custom tasks, the ID is provisioned as an environment variable.
URL Encoding
When using URL parameters in API requests, it’s important to know that special characters, such as spaces, percent signs (%), slashes (/), and parentheses (–), require URL encoding to transmit and interpret them correctly. Raw special characters in parameter values can disrupt the parsing of requests by the backend. This can cause parameters to be missed or misread and lead to errors, such as missing required parameters.
To prevent these issues, always encode special characters in parameter values before including them in a URL. For example, the value Average CPU (%/7d) should be encoded as Average%20CPU%20%28%25%2F7d%29. Standard tools, libraries, and browser APIs provide functions that automatically encode parameters. Proper URL encoding ensures compatibility and reliable data exchange between clients and APIs, especially when values include special symbols or spaces.